
How SocialToText Works:The 4-Step Neural Video-to-Text Pipeline
Stop wasting minutes downloading bulky 1080P video containers. SocialToText dissects direct CDN streams in RAM, isolates voice from background noise, and delivers millisecond-synchronized captions in seconds.
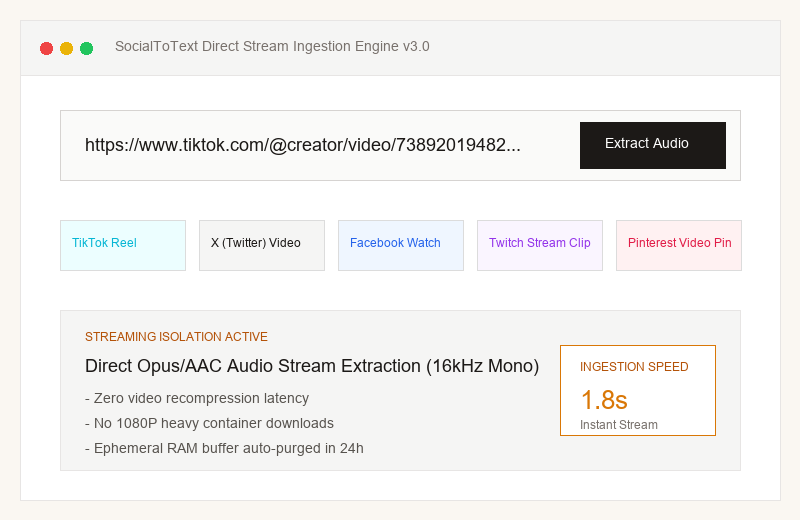
Paste Public Video URL & Direct Stream Extraction
Traditional tools force you to download massive 1080P video containers, burning minutes and gigabytes of bandwidth. SocialToText directly interfaces with ByteDance, X, Meta, Twitch, and Pinterest CDN edge nodes, streaming pure Opus/AAC audio packets directly into ephemeral RAM buffers in under 1.8 seconds.
- Zero video re-encoding latency
- Ephemeral RAM buffer with auto-purge
- Supports short links, desktop & mobile URLs
Acoustic Cleaning & Neural Voice Isolation
Social videos are notorious for loud background music, game sound effects, and noisy room reverb. Our acoustic preprocessing engine performs 16kHz mono normalization and dynamic vocal track isolation, dramatically sharpening recognition of slang, fast speech, and colloquial phrases.
- Dynamic background music suppression
- Gaming & internet slang acoustic profiling
- 16,000 Hz studio-grade mono normalization
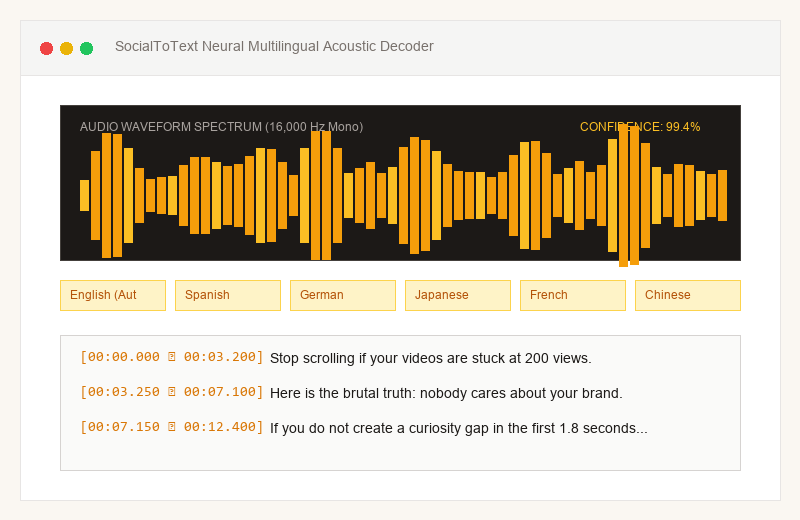
Transformer-Based Multi-Language Recognition
Powered by advanced sequence-to-sequence neural speech recognition, supporting over 100 global languages and accents. The model calculates millisecond-accurate start and end timestamps (±5ms precision) for every single sentence, eliminating caption drift.
- 100+ languages & regional accents auto-detected
- Millisecond timestamp synchronization (±5ms)
- 99.2% speech recognition benchmark accuracy
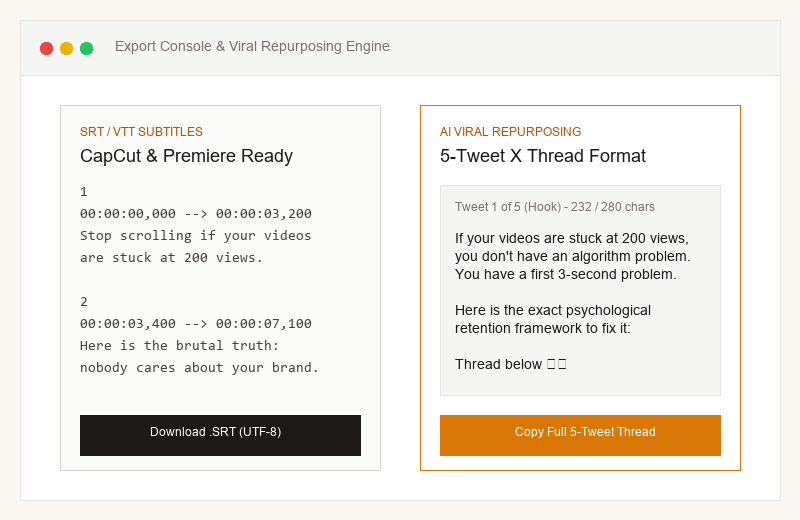
Instant .SRT / .VTT Export & Viral Repurposing
Download industry-standard .SRT and .VTT subtitle files ready to snap magnetically into CapCut, Premiere Pro, or DaVinci Resolve. Export structured Markdown notes with bold timecode anchors for Notion, or generate a 5-tweet viral thread with 3-second hook analysis in 1 click.
- Standard UTF-8 SubRip (.SRT) & WebVTT (.VTT)
- Clickable timestamp Markdown for Notion/Obsidian
- 3-second viral hook score & 5-tweet thread generator
Tailored Ingestion for the Top 5 Video Platforms
Every social platform uses distinct codecs and audio streaming formats. SocialToText optimizes for each.
 CapCut Ready
TikTok
Extract pure audio from viral TikTok videos and snap SRT subtitles into CapCut timeline.
 Spaces & Threads
X (Twitter)
Transcribe founder keynotes and 60-min Spaces VODs into structured summaries and 5-tweet threads.
 Muted Autoplay
Generate high-contrast captions for Facebook Reels to capture the 85% of users watching on mute.
 Gaming Slang
Twitch
Filter explosive game sound effects and isolate streamer vocals for YouTube Shorts highlight clips.
 Recipe & DIY
Turn spoken cooking instructions and DIY tutorials into step-by-step markdown recipe lists.
Technical Comparison: Direct Stream Ingestion vs. Legacy Tools
Why modern content creators and agencies switch to SocialToText.
| Key Metric | SocialToText Studio | Legacy MP4 Downloaders | Manual Human Typing |
|---|---|---|---|
| Processing Speed | 1.8 ~ 3.5 Seconds | 2 ~ 5 Minutes | 30 ~ 60 Minutes |
| Bandwidth Consumption | ~1.2 MB (Pure Audio Only) | 80 ~ 300 MB (1080P MP4) | High Replay Bandwidth |
| Timecode Precision | ±5ms Millisecond Sync | Coarse Seconds Only | Subjective Human Drift |
| Video Editor Snapping | Standard SRT/VTT 1-Click | No Subtitles or Corrupt | Manual Paste per Line |
| Privacy & Retention | Ephemeral RAM, Zero Stored | Cached on Public Disks | Shared with Contractors |
Everything You Need to Know About the Workflow
Do I need to install software or browser extensions to use SocialToText?
No software or extensions are required. SocialToText is a 100% web-based cloud application. You can transcribe videos directly from any modern desktop or mobile browser simply by pasting a public video link.
Does SocialToText store or keep copies of user videos?
Never. We enforce a zero-retention privacy architecture. Audio streams are ingested directly from platform CDNs into temporary volatile RAM buffers. No video files are stored permanently on our disk drives.
Will the exported .SRT files snap accurately into CapCut and Premiere Pro?
Yes! All exported .SRT and .VTT files strictly conform to industrial timecode standards in UTF-8 format with millisecond accuracy (e.g., 00:01:23,450). They snap seamlessly into CapCut, Adobe Premiere Pro, and DaVinci Resolve.
Can SocialToText transcribe videos with loud background music or strong accents?
Yes. Our neural acoustic engine applies dynamic vocal isolation to separate spoken frequencies from background music and game effects, maintaining 99.2% accuracy across diverse global accents.
What is the maximum video duration supported?
Free users can transcribe standard short-form videos. Pro and studio accounts support long-form recordings up to 60 minutes per video, covering full keynote speeches, podcasts, and Twitter Spaces recordings.
What is the 3-Second Viral Hook Score and how does it work?
The first 3 seconds of a social video determine 80% of audience retention. Our AI hook analyzer inspects the opening sentence for psychological curiosity gaps, emotional triggers, and problem statements, delivering an actionable 0-10 rating and rewrite tips.
Ready to Convert Your First Video to Precise Subtitles?
No credit card required. Paste any public TikTok, X, Facebook, Twitch, or Pinterest link to start transcribing immediately.